Your average improved. Some of your cases didn’t.
Rabbit Brain compares two checkpoints case by case and ranks the cases that got worse, including the ones a rising average hides. Every run writes a receipt another engineer can reproduce.
Apache-2.0. Runs on your machine; nothing leaves it. Tell your agent: “Review candidate checkpoint B against A on this case set with Rabbit Brain.”
000145_10One case in 200 got worse
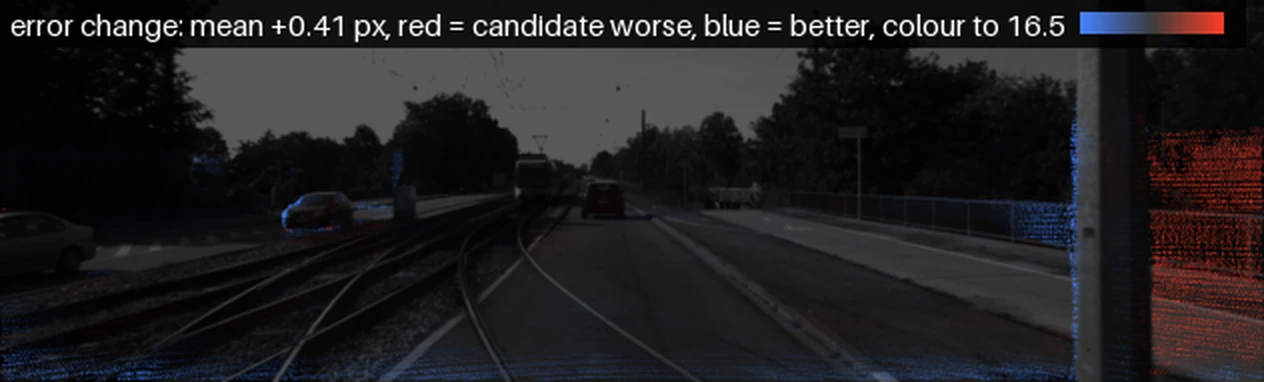
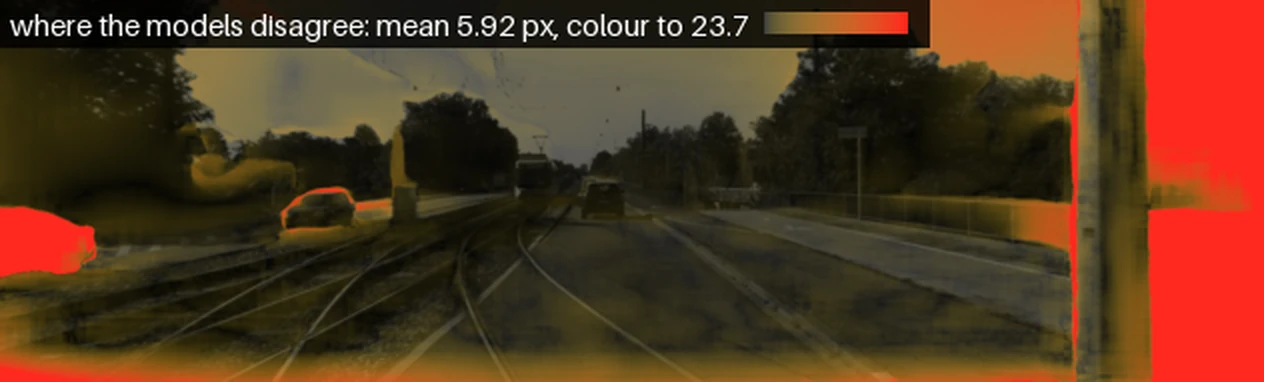
Mean error improved 71.8%. This case got worse by 0.41 px. Red marks where the candidate is worse: almost all of it is one object, the pole nearest the camera.
Compare two checkpoints, rank what got worse.
One label-free number per refinement iteration comes from a forward hook. No change to your model code.
Run or import
rb run --baseline A --candidate B, or rb import results.json with numbers your evaluator already produces.
See what needs a decision
Cases that got worse on error first, then cases that improved but never settled.
Keep the check
rb check save keeps a limit per case. rb check run fails CI on the next candidate.
RAFT-family flow through the built-in adapter, another model through one you write, or any paired lower-is-better metric from your own evaluator. See setup help.
What the refinement trajectory predicts.
A converged model keeps shrinking its updates. On the four public RAFT checkpoints, the size of the last few updates tracks a case’s error at a Spearman correlation of 0.88 to 0.92, on 200 cases each.
This is a correlation, not a verdict. A case still moving at the end is worth reviewing, but it is not necessarily wrong. The signal itself needs no labels; measuring it did.
Every review below was re-run on different hardware and a different torch build. Each verdict came out the same. Six of 200 cases sat close enough to a limit to change sides, which is why reports mark borderline findings.
What the receipt says
Verdict: Not ready: 1 error regression. Start with 000145_10 (5.48 → 5.89 px). The other 199 cases improved or stayed within 0.3 px. Checkpoints identified by sha256, RAFT at commit 2888e15, torch 2.4.1+cu124, seeds and the exact command recorded.
Two more reviews from the same night: raft-things → raft-kitti, 5.40 → 0.61 px, one case improved on error but did not settle; raft-things → raft-small, 155 regressions, the 39 worst ranked first by the trajectory test. All three are in examples/raft-kitti in the repository.
And a check on the receipt itself: all three reviews re-run on different hardware and a different torch build. On its reference cases the adapter matched RAFT’s own evaluation code to within 0.001 relative on all four checkpoints, The run makes that check on a sample of labelled cases and stops if it disagrees, unless you pass --skip-reference, which the receipt then records. Every verdict and error regression came out the same case for case. Six of the 200 cases sat close enough to a limit to change sides, which is why a report marks the findings that turn on a margin that thin.
Pricing
The tool is free and complete. Every run writes plain files into your repo, we never keep a copy, and nothing on this page unlocks anything.
pip install rabbit-brain. Run both checkpoints, or import numbers from the evaluator you already have. Ranked findings, saved checks that follow case IDs across releases and fail CI, and --json on every command.
The limits it ships with are generic. Every report plots them against your own data so you can see where one falls. Everything the tool writes stays in your repo.
Get the toolTeam workspace, US$99 per workspace per month. Not available yet, and not for sale until it works. It adds the approved baseline CI measures against, versioned release policy, and retained verdicts. Inference stays on your machine.
Join the waitlist for the team workspace.
The command line tool is free and complete. The team workspace is not built yet. When it is, it will add:
- The approved baseline that CI measures the next candidate against
- The release policy, under version control, with its history
- Every gate verdict, kept across builds
- A second person who can open the review at all
Join the waitlist and we will email you when it is ready. We also use the list to decide what to build first.